Key Options at a Glance
The options you will use most. Everything can be given on the command line (--level 3) or in an options file
(level = 3); command-line flags override the file. The complete list with every default is in CONFIGS.md.
A printable summary is available as a pdfquick reference (PDF).
data-obfuscator run --input pk.csv --output ./masked --level 2 --seed 2026
data-obfuscator run --config study_options.txt
run: masking one dataset
| Option | Default | What it does |
|---|---|---|
--input FILE |
required | The dataset (CSV, TSV, semicolon or whitespace delimited). |
--output DIR |
required | Output folder. Must be new or empty unless --overwrite. |
--config FILE |
none | Options file. |
--level 1-4 |
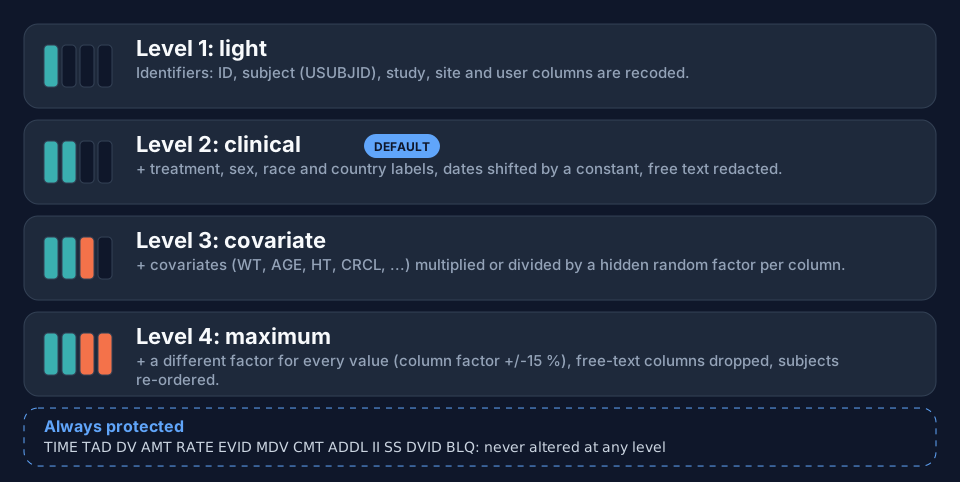
2 | How much to mask (identifiers, + labels/dates/text, + covariates, maximum). |
--seed N |
42 | Random seed. Same input + options + seed = identical output. Use your own seed when privacy matters. |
--id-style |
sequential | Style of recoded IDs: sequential, padded or hashed. |
--date-shift-days |
1-100 | A window to draw the shift from (1-100), or one fixed number of days (23.6). |
--scale-range MIN-MAX |
1-20 | Range of the random factor for scaled columns (levels 3 and 4). |
--scale-columns |
none | Extra numeric columns to scale. Covariates such as WT and AGE are scaled automatically. |
--keep / --drop |
all / none | Columns to keep, or to drop. |
--protect |
TIME, DV, AMT, EVID, ... | Columns that must never be altered. |
--freetext-columns, --drop-freetext |
auto | Free-text columns to redact, or drop instead of redacting. |
--rename-columns, --rename-except |
none | Rename listed columns (or every column except the listed ones). |
--write-keymap BOOL |
true | Write the private key. Without it the masking can never be undone. |
--overwrite |
off | Allow a non-empty output folder. |
Each --level includes everything the one before it masks:
Telling the program which column is which
Column roles are detected from the names (ID, USUBJID, STUDYID, SITEID, ARM, SEX, DATE, WT, ...). When
your names differ, say so; several names per role are allowed:
--id-column, --subject-column, --study-column, --site-column, --treatment-column, --user-column,
--date-columns, --sensitive (extra identifiers to recode).
Unusual files
--delimiter (auto, comma, tab, space, semicolon), --no-header with --columns, --comment-chars.
run2: masking several datasets together
Takes the same options as run where they apply, with these differences:
| Option | What it does |
|---|---|
--input FILE (repeat), a folder, or input = lines |
The datasets to mask together (for example four ADaM files). |
--level 1-3 |
Level 4 is not available (it could not be traced through a merged dataset). |
--date-shift-days |
Drawn as a whole number of days, one value for every dataset. |
--adam-hints BOOL |
Recognise ADaM names (ADT, ADTM, TRT01P, ...). On by default. |
| not available | keep and column renaming (the LLM needs the ADaM column names); use --drop instead. |
reverse: undoing the masking
| Option | What it does |
|---|---|
--input FILE |
The masked dataset (or the master dataset built from run2 files). Rows and columns may be in any order. |
--keymap FILE |
keymap.txt or keymap2.txt (default: next to the input). The program recognises which it is. |
--keymap-columns FILE |
Level 4 only: keymap_columns.txt (default: next to keymap.txt). |
--output DIR |
Where to write restored.*, reverse_report.txt and reverse.log (default ./restored). |
--only / --skip |
Undo only, or all but, these parts: rename, scaling, dates, recoding. |
--strict |
Stop with an error instead of approximating or leaving unknown values unchanged. |
--map COMBINED=SOURCE |
run2 key only: where a renamed or merged column came from, for example ID=USUBJID, DV=AVAL, or with a condition DV=PCSTRESN:DVID=1. |
tokens
data-obfuscator tokens --input file.csv --output ./folder estimates token counts for the main LLM families.
Global options
--version (banner and a description of the program), --help (also available for every command), --no-color.
A small options file
# study_options.txt
input  = pk_study.csv
output = ./masked
level  = 3
seed   = 20261012
date_shift_days = 1-100
study_column   = STU, STUDYID
drop = INVESTIGATOR
Run it with data-obfuscator run --config study_options.txt.
Download the example options file: txtstudy_options.txt